

Resources and insights
Our Blog
Explore insights and practical tips on mastering Databricks Data Intelligence Platform and the full spectrum of today's modern data ecosystem.
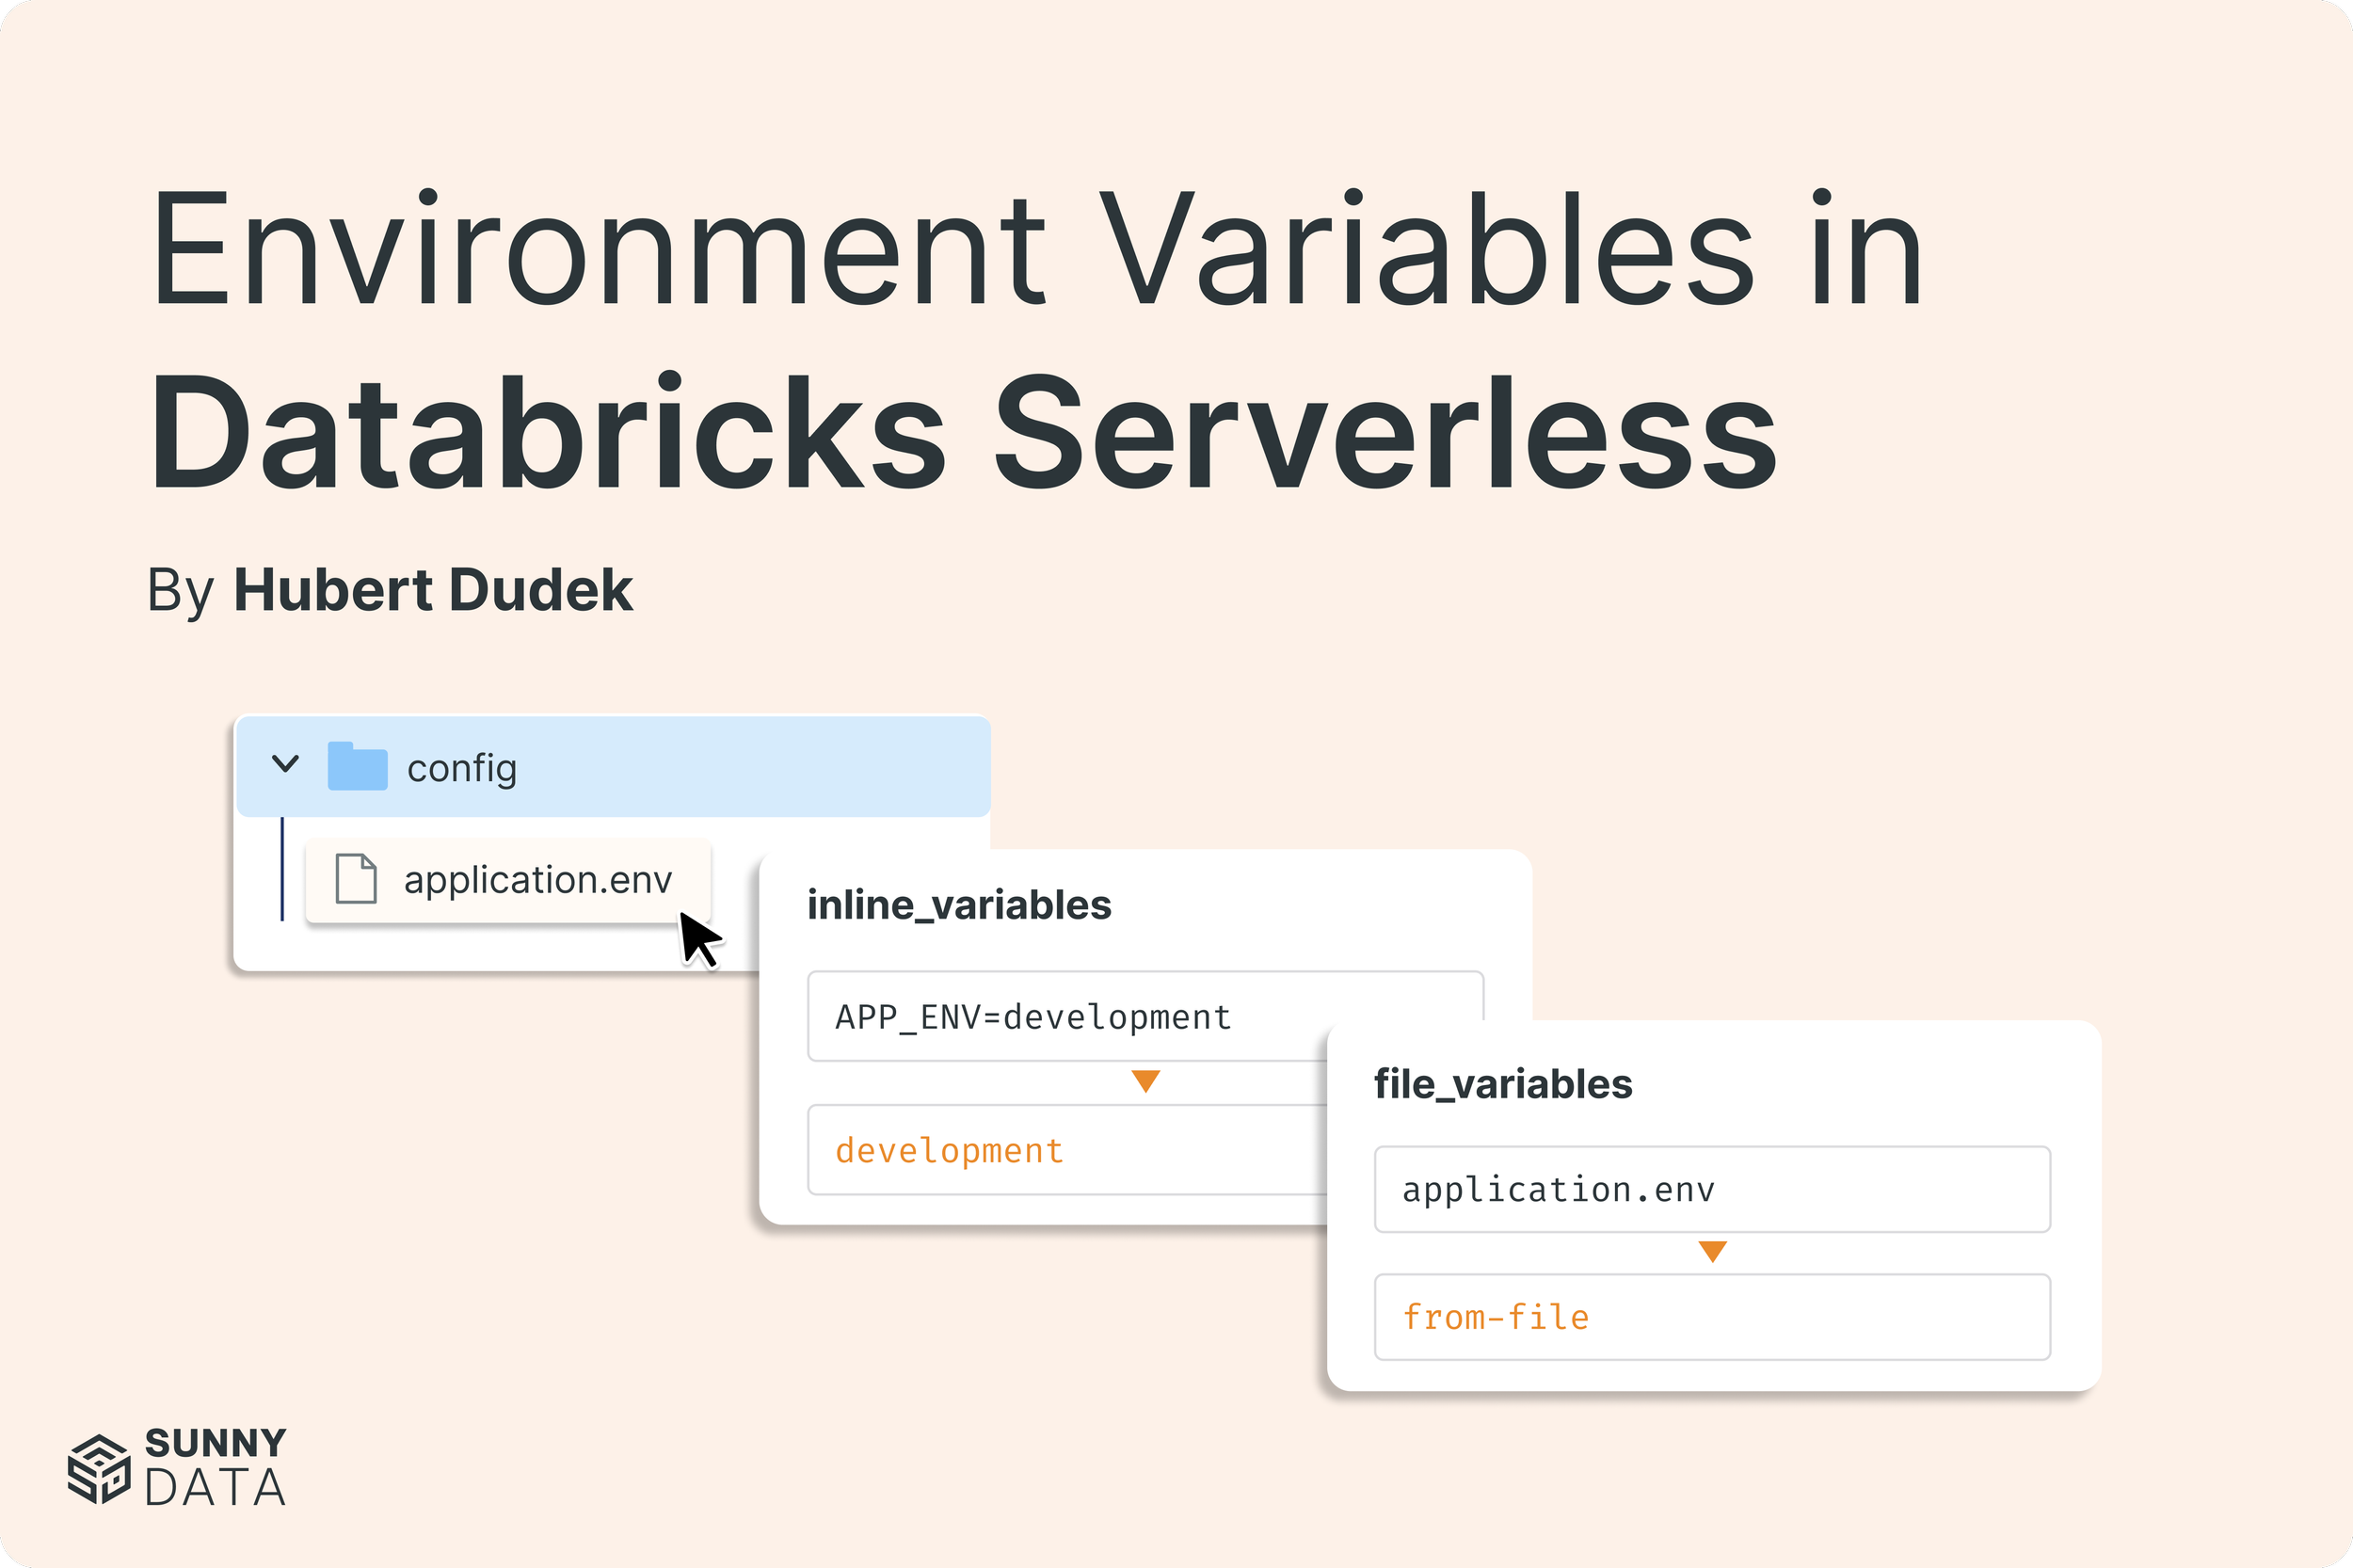


Environment Variables in Databricks Serverless
Copying the same job for dev, staging, and prod invites drift and leaked secrets. Here’s how serverless environment variables let one job definition carry different settings per task, with a working three-task demo.

Databricks DABs CI/CD: 4 Ways to Automate Your Deployments
Every CI/CD pipeline eventually needs something to run after deployment: initial setup, config syncs, validation checks. job_runs in Databricks Asset Bundles handles all of it natively, and you can use it to block a production update when validation fails.

5 Databricks Patterns That Look Fine Until They Aren't
Five common Databricks coding patterns — including undocumented API calls, manual SparkSession instantiation, and hardcoded Spark configs — that pass code review but fail silently in serverless environments or during platform migrations. For each anti-pattern, this post explains why it breaks and shows the correct native Databricks approach using DABS, the Databricks SDK, and dynamic job parameters.

Why Your Databricks Upgrade Is Incomplete If You're Still Running ADF
Still running ADF after moving to Databricks? Here's why it happens, what it's costing your governance story, and how Lakeflow Jobs closes the gap.

Databricks Workflow Backfill
Use Databricks Workflow backfill jobs to reprocess historical data, recover from outages, and handle late-arriving data efficiently.